

Maximum of 25 job preferences reached.
Top Remote Senior Site Reliability Engineer Jobs in Chicago, IL

Artificial Intelligence • Cloud • Information Technology • Software
Design and operate large-scale GPU infrastructure for distributed AI training, ensuring reliability, performance, and efficient customer partnerships.
Top Skills:
AnsibleCudaDeepspeedFsdpGpuHelmInfinibandKubernetesLinuxMegatronNcclNvidia A100Nvidia B200Nvidia H100NvlinkPyTorchRoceTerraform

Real Estate • Financial Services • PropTech
Lead AWS-based SRE activities for products migrated from on-prem: ensure reliability, observability, automation, CI/CD (GitOps), Kubernetes/EKS operations, Terraform IAC, database/RDS administration, networking and security, and collaborate with development and platform teams to optimize SaaS operations.
Top Skills:
AmiArgocdAWSAws Elastic BeanstalkAws Transfer FamilyAws Well-Architected FrameworkAzure DevopsBashCloudwatchCurlDockerEc2EksFluxcdGitGitopsHTTPIstioKubernetesLinkerdLoad Balancer (Elb/Alb)PowershellPythonRdsService MeshSQLTerraformWget

Artificial Intelligence • Information Technology • Consulting
The Linux Systems Administrator will maintain and troubleshoot Linux systems, support network services, and work on systems integration while collaborating with infrastructure teams.
Top Skills:
DhcpDnsLinuxNtpPython

Digital Media • Gaming • Information Technology • Software • Sports • Esports • Big Data Analytics
Lead reliability, scalability, and operational excellence of large-scale database platforms across cloud and on-prem. Build automation-first database infrastructure (Kubernetes operators, IaC, GitOps), drive monitoring/SLOs, incident leadership, performance and cost optimization, and partner with application teams on safe schema/migration practices. Mentor engineers and evaluate AI-assisted workflows to improve productivity and reliability.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorDatabase OperatorsEksFluxcdGithub CopilotGitopsGkeGoKubernetesMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform
2 Months AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Build and operate reliable, scalable production infrastructure for GitLab’s user-facing services. Responsibilities include developing infrastructure automation and tooling, managing Kubernetes deployments, maintaining infrastructure as code, supporting CI/CD and GitOps, participating in on-call and incident response, improving observability and SLOs, troubleshooting production systems, and documenting operational practices. The role spans Intermediate through Senior Staff levels and requires strong software engineering, cloud, reliability, and asynchronous collaboration skills.
Top Skills:
AlertingAWSCi/CdGCPGitopsGoInfrastructure As CodeKubernetesLoggingMetricsRubySlisSlosTerraform

Social Media • Software
Design, implement, and operate infrastructure for high-scale production systems serving millions of users. Own reliability, observability, incident response, deployments, capacity planning, cost management, and operational excellence across bare-metal and cloud environments. Develop automation and performance tooling, improve production readiness, manage vendors, lead incident reviews, and mentor engineers on reliability and distributed-systems practices.
Top Skills:
Bare-Metal ServersCloud ServicesDatabasesDistributed SystemsGoKubernetesLinuxNetworkingObservability SystemsStorage Systems

Other
Build and operate AWS GovCloud environments within FedRAMP boundaries, including multi-account infrastructure, guardrails, logging, security tooling, and Terraform provisioning. Develop automated fleet release, patching, verification, CI/CD, compliance evidence, telemetry, SLO, and alerting systems. Support VM and appliance fleets at scale, participate in on-call, and engineer recurring incident causes away. The role also requires compliance-as-code, continuous monitoring, and test harnesses validating operational state.
Top Skills:
AlertingArtifact ManagementAws ConfigAws GovcloudCi/CdDashboardsFedrampFipsGrafanaKubernetesOpaOpentelemetryOscalSecurity ScanningSlosTelemetryTerraform

Cloud • Security • Cybersecurity
Owns operational capabilities for FedRAMP-regulated cloud environments, including monitoring, alerting, backup and recovery, continuous compliance evidence, incident response, and automation. The role leads major incident command, improves runbooks and operational standards, supports client-facing service delivery, partners on transitions to managed operations, and mentors engineers. Requires deep cloud operations, observability, infrastructure-as-code, resilience engineering, security-control frameworks, and senior escalation experience.
Top Skills:
AnsibleAWSAzureCi/CdGCPGoInfrastructure As CodeJSONOscalPolicy As CodePythonSIEMTerraform
Fintech • Financial Services
Build and govern reliable, scalable production infrastructure across cloud environments. Responsibilities include DevOps guardrails, CI/CD, Terraform-based infrastructure, deployment strategies, developer platforms, observability, SLOs, incident response, capacity planning, automation, chaos engineering, and cloud optimization. The role partners with engineering teams to improve resilience and supports .NET services across Windows and Linux.
Top Skills:
.NetAWSAws App MeshAws Fault Injection SimulatorAws Secrets ManagerBashCdnsCi/CdCloudwatchDatadogDnsDockerEcsElk StackGitopsGoGrafanaGremlinHashicorp VaultIstioLinkerdLinuxLitmusNew RelicPowershellPrometheusPythonTerraformWindows
Cloud • Security • Software • Cybersecurity
Ensure reliability, scalability, and usability of network infrastructure for Akamai Connected Cloud. Define requirements and SLOs, build automation and CI/CD pipelines, collaborate with dev/QA to improve code and stability, troubleshoot complex network issues (on-call), and mentor teammates while driving architectural standards.
Top Skills:
AnsibleArgocdBashBirdChefFrrGithub ActionsGoGobgpJenkinsLinux NetworkingPuppetPythonSalt Stack

Artificial Intelligence • Information Technology • Consulting
Lead end-to-end deployment and operation of cloud infrastructure and Symmetri environments for US customers. Provision, configure, monitor, maintain, upgrade, and troubleshoot cloud, single-tenant, on-premises, and air-gapped environments. Manage Kubernetes, networking, IAM, infrastructure as code, resource planning, incident response, runbooks, and root-cause analysis. Represent the company in customer security reviews and help establish US deployment and operations standards and teams.
Top Skills:
AWSAws CdkAzureDnsGitIamKubectlKubernetesLoad BalancingOpentofuPulumiPythonTerraformTerragruntVnetsVpc
Professional Services • Consulting
Own and improve CI/CD, developer tooling, agent harnesses, Kubernetes infrastructure, observability, cost management, and incident-response practices. Build platform capabilities that reduce engineering toil and improve delivery speed for conversational AI products. Participate in an on-call rotation for core infrastructure and help shape reliable, scalable systems across a fully remote engineering organization.
Top Skills:
AlertingCi/CdHelmIncident ManagementKubernetesLlmsLogsMetricsMonitoringNode.jsObservabilityPythonTerraformTracingTypescript
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free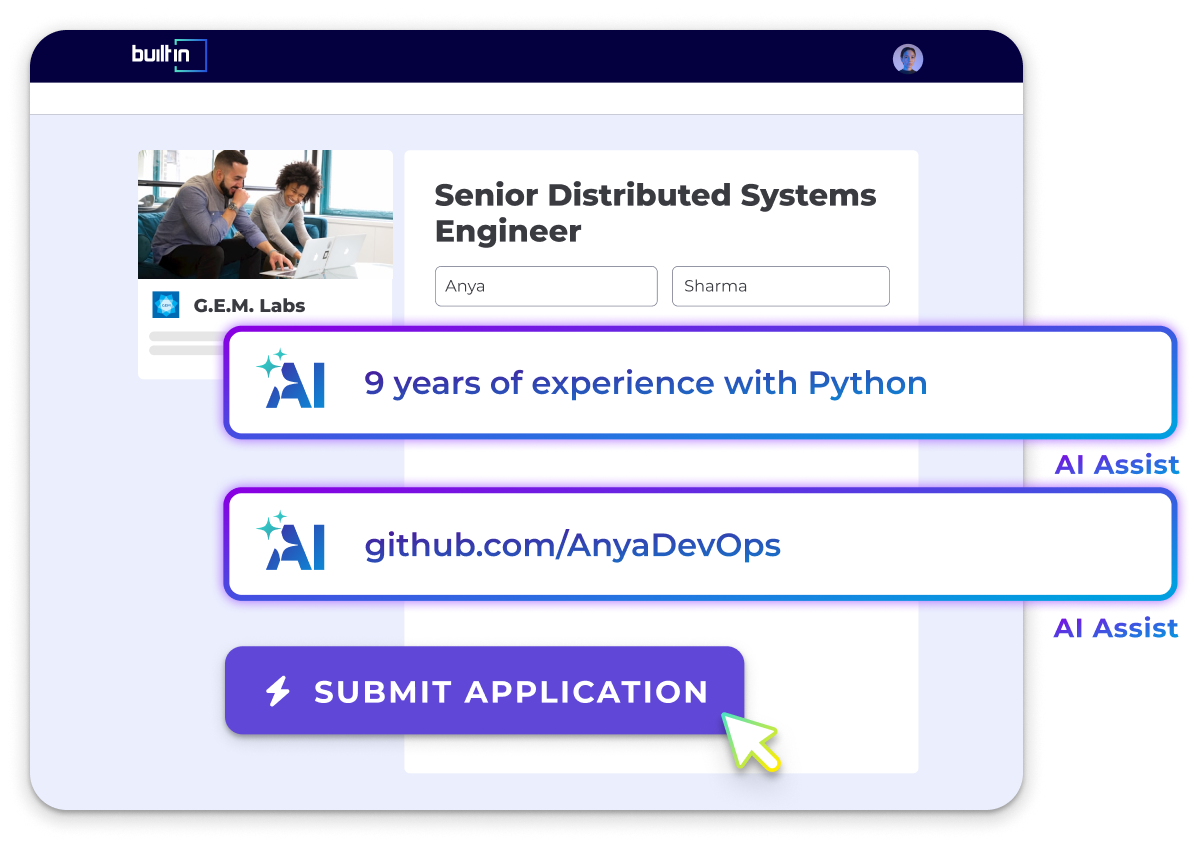

Consumer Web • Gaming • Mobile • News + Entertainment • Software
Own database reliability, scalability, and operational excellence across cloud and on-premises environments. Build automated Kubernetes-based database platforms, infrastructure tooling, failover and backup systems, and self-healing capabilities. Lead observability, performance optimization, capacity planning, incident response, and safe migration practices. Partner with application teams, leverage AI for operational improvements, mentor engineers, influence architecture, and drive technical strategy for highly available database infrastructure.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorEksFluxcdGithub CopilotGitopsGkeGoKubernetesKubernetes OperatorsMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform

Reposted 3 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
As a Senior Site Reliability Engineer, you'll design and build complex systems, support Atlas platform operations, automate processes, and ensure high availability of services.
Top Skills:
AWSAzureDnsGCPGoHTTPLinuxPythonRubyTls

Cloud • Fintech
Build and operate reliable, scalable cloud applications through automation, infrastructure as code, CI/CD, monitoring, incident response, capacity planning, and SLO management. Collaborate with software engineers on resilient system design, support development environments, improve operational processes, and participate in 24x7 on-call rotation. The role requires expertise with AWS, Kubernetes, Terraform, Docker, networking, and observability, along with mentoring and leadership in SRE practices.
Top Skills:
Amazon CloudwatchAmazon EksAmazon RdsAWSAzureCi/CdDnsDockerDocker DesktopGoGCPHTTPKubernetesmacOSTcp/IpTerraformTypescriptWindows
Fintech • Software • Financial Services
Lead the SRE function for NinjaTrader’s trading platform, ensuring availability, scalability, performance, and 99.95% uptime. Responsibilities include managing Kubernetes services, resolving production incidents, participating in a 12x7 on-call rotation, automating deployments and operational tasks, designing monitoring and alerting systems, establishing SLIs/SLOs, using Terraform for infrastructure automation, and implementing cloud security and compliance practices. The role also mentors engineers and collaborates cross-functionally on reliable platform delivery.
Top Skills:
AnsibleAWSAzureBashDatadogDockerGCPGithub ActionsGoGrafanaHelmKubernetesPci DssPrometheusPythonSoc 2Terraform
Artificial Intelligence • Cybersecurity
Own and evolve the company-wide SRE strategy, reliability standards, observability practices, incident management, service ownership, SLOs, and on-call operations. Lead cross-functional reliability initiatives, establish dashboards, alerts, runbooks, and escalation paths, improve production readiness and incident response, and operate large-scale distributed systems across AWS and Kubernetes. Participate in a 24/7 on-call rotation and help shape the SRE function.
Top Skills:
Argo CdAWSDatadogGitlab CiGitopsGrafanaKubernetesNew RelicPythonTerraform

Healthtech • Pharmaceutical
Own the reliability, availability, performance, observability, and security of Ophelia’s GCP telehealth platform. Define SLOs, improve monitoring and incident response, expand Terraform infrastructure, strengthen CI/CD, manage disaster recovery, and address latency and Cloud Run performance. Lead on-call maturity, HIPAA/SOC 2 infrastructure controls, and reliability education for engineers. Use AI-assisted tools for automation and incident triage while partnering with technical and non-technical stakeholders.
Top Skills:
BigQueryClaudeCloud RunFirebaseFirebase AuthenticationFirebase HostingFirestoreGeminiGithub ActionsGoogle Cloud OperationsGoogle Cloud PlatformIamNode.jsPagerdutyPythonReactShell ScriptingSQLTerraformTypescript

Security
Own infrastructure reliability across GCP, Kubernetes, PostgreSQL, and hundreds of cloud projects. Build automation and software that eliminate toil, reduce manual on-call work, address latency and reliability trade-offs, and provide system health visibility. Lead infrastructure projects, define service-level objectives with product teams, improve reliability practices, and develop production systems for agent-first applications.
Top Skills:
GCPKubernetesPostgres

Edtech • Fintech • Information Technology • Software
Operate and improve AWS production infrastructure, infrastructure as code, Kubernetes workloads, observability, CI/CD, and incident response. The role investigates root causes, strengthens application resilience, automates operational tasks, supports database and performance reliability, maintains documentation, and participates in 24/7 on-call rotations. The engineer owns scoped reliability projects and collaborates with product engineering teams on resilient, secure, and compliant systems.
Top Skills:
Amazon EksAmazon RdsAWSCircleCIDatadogGithub ActionsKubernetesLinuxNew RelicOpensearchPostgresRedisRubyRuby On RailsTerraform

Information Technology • Security • Cybersecurity
Own production operations and highly available cloud infrastructure for regulated government environments. Lead incident response, root-cause analysis, disaster recovery testing, compliance operationalization, audit readiness, vulnerability management, and continuous monitoring. Build automation, secure CI/CD pipelines, infrastructure-as-code, observability, and compliance tooling across Kubernetes, Linux, containers, and cloud platforms. Partner with security, compliance, and engineering teams to improve reliability, deployment safety, and regulatory sustainment.
Top Skills:
Aws GovcloudBashCi/CdDod Il4Dod Il5FedrampGitopsGoGrafanaKubernetesLinuxNist 800-53PrometheusPythonStigTerraformUnixZero Trust

Cloud • Software • Analytics
Develop and operate Arista’s FedRAMP CloudVision SaaS platform at scale. Responsibilities include improving reliability, scalability, observability, autoscaling, disaster recovery, capacity planning, CI/CD, network architecture, cost optimization, and cloud application security. The role develops and manages Kubernetes-native services, distributed databases, and automation using technologies such as GCP, GKE, Go, Python, Ansible, Pulumi, and Bash. Participation in a FedRAMP on-call rotation is required.
Top Skills:
AnsibleBashCi/CdDistributed DatabasesFedrampGoGoogle Cloud Platform (Gcp)Google Kubernetes Engine (Gke)KubernetesPulumiPythonSaaS
Fintech • Real Estate • Software
Lead reliability and observability efforts across the org: design and maintain Kubernetes and AWS infrastructure, build CI/CD pipelines, drive IaC standards (Terraform/Crossplane), partner with 16+ teams to roll out tools and processes, participate in on-call rotation and incident response, and use AI tools to accelerate work.
Top Skills:
Ai ToolsArgoAurora PostgresAWSCi/Cd PipelinesCrossplaneDatadogDocumentdb (Mongo)EcsEksGithub ActionsHelmKubernetesMongoDBPostgresRdsTerraform
One Month AgoSaved
Cloud • Security • Software • Cybersecurity
Develop and operate Akamai’s Linux-based cloud infrastructure, including bare-metal and virtual machine platforms, kernels, operating systems, and KVM/QEMU virtualization. Build software, automation, observability, and infrastructure enhancements at scale; troubleshoot complex distributed-system issues; collaborate across engineering and operations; mentor team members; and participate in on-call service restoration.
Top Skills:
AnsibleChefKubernetesKvm/QemuLinuxLinux KernelNested VirtualizationPuppetSaltstack
Other
Lead platform infrastructure reliability initiatives for a microservices-based cloud SaaS solution. Design scalable, automated, observable infrastructure; define platform roadmaps; guide engineering teams through design reviews; reduce operational toil; build monitoring and alerting; and participate in on-call incident response. The role uses AWS, Kubernetes on EKS, Istio, infrastructure-as-code, GitLab, Argo CD, and Datadog.
Top Skills:
Amazon EksArgo CdAWSAws CdkDatadogEc2GitlabIstioKubernetesRdsS3Terraform

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Chicago, IL Companies Hiring Remote Senior Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
