

Maximum of 25 job preferences reached.
Top Senior Site Reliability Engineer Jobs in Chicago, IL
Fintech • Machine Learning • Payments • Software • Financial Services
Lead resilience engineering for large-scale cloud infrastructure. Responsibilities include defining architectural vision, automating platform operations, managing incidents and root-cause analysis, governing multi-cloud IaC, establishing SLOs, mentoring SRE teams, and optimizing capacity, costs, and FinOps strategy. The role also drives observability, security governance, distributed systems reliability, and production platform scalability across engineering organizations.
Top Skills:
AWSCi/CdGCPGenerative AiInfrastructure As Code (Iac)KubernetesAzureSecrets ManagementServerlessZero Trust
Financial Services
Builds, maintains, monitors, and optimizes applications and infrastructure using site reliability engineering practices. Responsibilities include designing deployment and reliability approaches, implementing CI/CD and infrastructure as code, monitoring service-level objectives, resolving complex operational issues, improving availability and scalability, and using validated enterprise AI capabilities for incident triage and reliability analysis. The role also guides peers and promotes SRE best practices.
Top Skills:
.NetCloud InfrastructureConfiguration As CodeContainer OrchestrationContainersContinuous DeliveryContinuous IntegrationInfrastructure As CodeJavaNetwork As CodeObservabilityPythonService Level ObjectivesSpring Boot

Fintech • Information Technology • Payments • Sharing Economy • Financial Services • Cryptocurrency
Leads reliability, scalability, performance, and security for large-scale cloud systems. Designs AWS infrastructure with Terraform, automates CI/CD and operational workflows, establishes SLOs, manages incident response and disaster recovery, develops monitoring and observability solutions, and builds internal tools. Partners with engineering teams on architecture and reliability practices, conducts code reviews, mentors SREs, and supports compliance, vulnerability management, and security integration.
Top Skills:
Agentic ApplicationsAmazon Api GatewayAmazon AuroraAmazon CloudfrontAmazon CloudwatchAmazon DynamodbAmazon EbsAmazon Ec2Amazon EcsAmazon EfsAmazon RdsAmazon Route 53Amazon S3Amazon VpcAWSAws FargateAws LambdaAws X-RayChaos EngineeringCi/CdDastDatadogDistributed SystemsDockerEvent-Driven SystemsGitlabGitopsGrafanaIamInfrastructure As CodeJavaKubernetesLlmsMicroservicesNew RelicNode.jsOwasp Top 10PythonSastServerless ArchitecturesSplunkTerraform

Artificial Intelligence • Big Data • Healthtech • Mobile • Wearables • Analytics
Build and operate reliability systems for a cardiovascular data platform, including monitoring, SLIs, SLOs, incident response, automation, and observability. Investigate end-to-end failures across devices, connectivity, mobile applications, firmware, and cloud services. Analyze fleet-level reliability using Python, SQL, and BigQuery; automate manual checks; conduct postmortems; and improve telemetry to ensure complete, trustworthy clinical data delivery.
Top Skills:
AndroidAWSAzureBigQueryBluetooth Low EnergyCellular ConnectivityDatadogEmbedded FirmwareFmeaFracasGCPGrafanaIec 60812Iso 13485PythonSQLWi-Fi
Financial Services
Builds, maintains, monitors, and optimizes applications and cloud infrastructure for availability, reliability, and scalability. Designs automated CI/CD and infrastructure-as-code solutions, implements observability and SLOs, troubleshoots incidents and networking issues, and reduces operational toil. The role also guides teammates in SRE best practices, uses authorized AI tools for incident analysis, and collaborates across teams to proactively resolve complex platform and business problems.
Top Skills:
Amazon EcsAnsibleAWSDatadogDockerDynatraceGitlabGrafanaJenkinsKubernetesLinuxPrometheusPythonSplunkTerraformWindows
Financial Services
Design, implement, and maintain reliable, scalable cloud infrastructure and deployment pipelines. Monitor and optimize application availability using observability, SLOs, and telemetry. Automate infrastructure/configuration as code, troubleshoot containers and networking, collaborate across teams, and apply enterprise-authorized AI to accelerate incident triage and reliability improvements while ensuring data sensitivity.
Top Skills:
.NetCi/CdCloudContainersDockerEnterprise AiJavaKubernetesMonitoringNetworkingObservabilityPythonService Level Objectives (Slo)Spring BootTelemetry
Artificial Intelligence • Professional Services • Business Intelligence • Consulting • Cybersecurity • Generative AI
Design and implement reliable, scalable IT infrastructure; automate processes; monitor systems; resolve incidents; conduct performance and load testing; optimize cloud environments; maintain storage architecture; and lead continuous improvement. The role requires troubleshooting complex system issues, developing automation solutions, managing incidents, collaborating across teams, mentoring others, and supporting secure business operations across AWS, Google Cloud, and Microsoft Azure.
Top Skills:
AWSGoogle Cloud PlatformAzure

Artificial Intelligence • Big Data • Healthtech • Information Technology • Machine Learning • Software • Analytics
Lead SRE practices for highly available cloud-native platforms across AWS, Azure, and Kubernetes. Build observability, dashboards, alerting, infrastructure automation, CI/CD, GitOps, and self-healing capabilities. Lead incident response, root cause analysis, and remediation while improving reliability, scalability, and operational excellence. Partner with engineering, architecture, security, and platform teams, drive AI-enabled operations, and mentor engineers on SRE and cloud-native best practices.
Top Skills:
AksArgocdAWSAws ApmAzureAzure DevopsBashDatadogDynatraceEksFluxGCPGithub ActionsGitopsGkeGrafanaIamJenkinsKubernetesOpentelemetryPowershellPrometheusPythonSplunkTerraform
Healthtech • Pharmaceutical
Lead Site Reliability Engineer responsible for reliability, availability, observability, incident response, and operational excellence across large-scale public-facing software. The role defines SLOs and error budgets, leads capacity and resilience testing, improves infrastructure using Terraform and Kubernetes on AWS, automates operational workflows, and mentors engineers. Responsibilities also include production readiness reviews, architecture guidance, on-call support, postmortems, and establishing reliability standards across the technology organization.
Top Skills:
AWSClaude CodeDatadogGoKubernetesMcpPythonTerraform
Fintech • Software • Financial Services
Monitor and maintain enterprise application and infrastructure performance, availability, and stability. Administer observability tools, manage alerts and scheduled jobs, perform incident triage, coordinate outage communications, troubleshoot Linux and infrastructure issues, maintain monitoring dashboards, document procedures, produce reports, and follow ITIL-based escalation and problem-management practices in a 24/7 environment.
Top Skills:
DatadogElkGrafanaItilLinuxPrometheusUnix

Automotive • Hardware • Internet of Things • Mobile • Software • App development • PropTech
Designs, engineers, and automates highly available cloud infrastructure and platforms for a global IoT service. Responsibilities include evolving PaaS implementations, managing Kubernetes and infrastructure-as-code solutions, monitoring and troubleshooting security and infrastructure events, conducting root-cause analysis, collaborating on architecture and security, and mentoring junior engineers. The role also supports technology roadmaps, cloud cost optimization, and infrastructure initiatives across distributed teams.
Top Skills:
Active DirectoryAgileArgo CdAWSBashDatadogFirewallsGoGrafanaIso 27001KubernetesLinuxNew RelicPowershellPrometheusPythonScrumSIEMTerraformVpcWindows

Fintech • Information Technology • Insurance • Financial Services • Big Data Analytics
Leads architecture, modernization, optimization, and reliability initiatives for mainframe CICS, MQ, and z/OS Connect environments. Provides technical direction across development and operations teams, establishes governance and change processes, tunes performance using telemetry, resolves incidents, and develops modernization roadmaps. Collaborates with stakeholders and enterprise architects to deliver secure, scalable, high-availability solutions while evaluating automation, cloud integration, and AI technologies.
Top Skills:
AnsibleCicsCobolDevOpsIbm MqIbm Z/OsOpenshiftPythonRed Hat Ansible Automation PlatformZ/Os ConnectZlinux
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free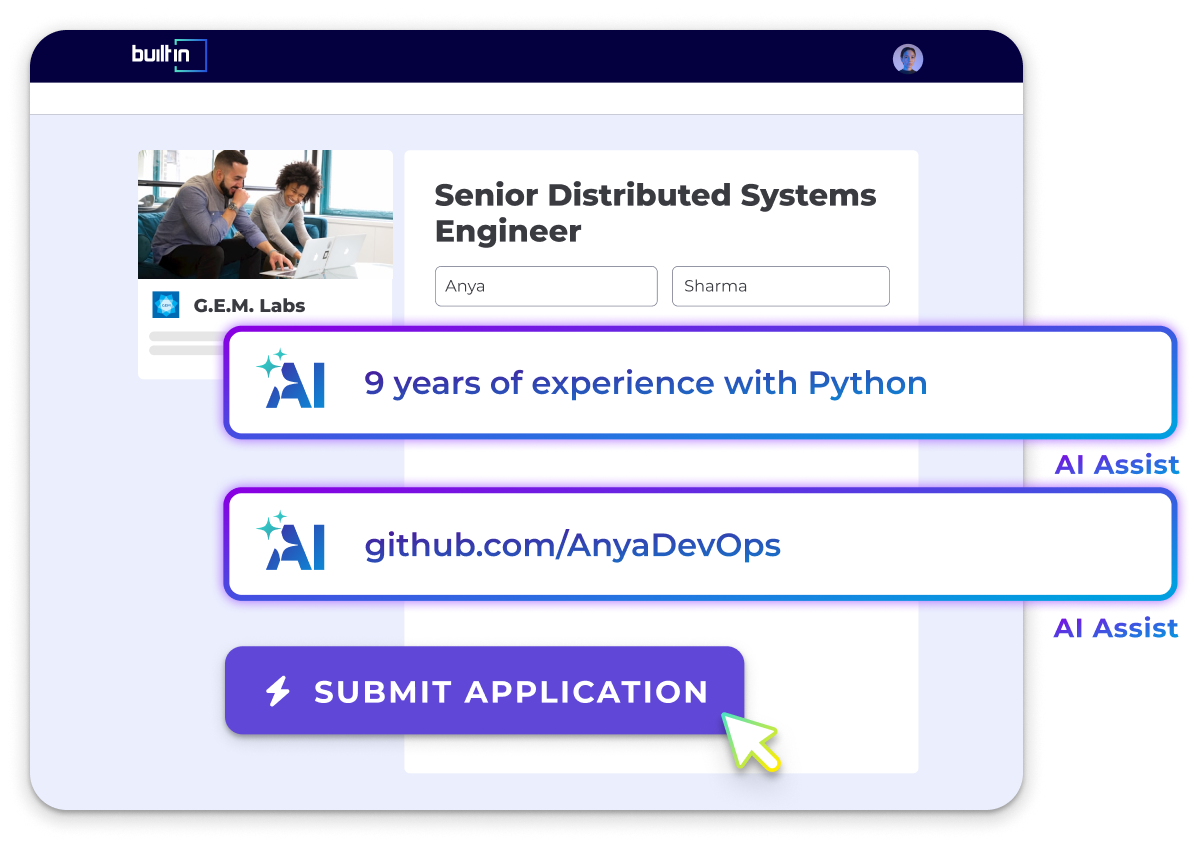

Big Data • Cloud • Information Technology • Legal Tech • Software
Maintain and improve AWS production infrastructure, infrastructure-as-code, CI/CD pipelines, monitoring, observability, and security controls. Participate in on-call support, troubleshoot incidents, track SLOs and cloud costs, write post-incident reports and runbooks, and collaborate with engineering teams on reliable feature delivery. Support SOC 2 compliance, access controls, encryption, audit logging, vulnerability management, and AI workloads on Amazon Bedrock.
Top Skills:
Amazon BedrockAmazon EcsAWSAws CdkAws CloudformationCi/CdCloudwatchDatadogDockerEc2GoGrafanaHipaaIamKubernetesLambdaPrometheusPythonRdsS3Soc 2TerraformVpc
21 Days AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Provide technical direction for GitLab Dedicated, a managed single-tenant SaaS platform. Lead architecture and transformation across resilience, failover, tenant orchestration, change management, automation, and platform integrations. Identify systemic reliability and scalability risks, establish reusable platform patterns, strengthen service ownership, and guide cross-team technical decisions. Mentor senior engineers and advance engineering excellence across the organization.
Top Skills:
Cloud InfrastructureDevsecopsDistributed SystemsGoInfrastructure As CodeObservabilityPythonRuby
Reposted One Month AgoSaved
Artificial Intelligence • Professional Services • Business Intelligence • Consulting • Cybersecurity • Generative AI
Leads teams designing and deploying AI-driven enterprise and cloud security solutions. Responsibilities include developing machine learning systems, integrating data infrastructure and pipelines, performing advanced modeling and analysis, and building AI applications with Python, Java, and C++. The role involves client engagement, strategic problem-solving, stakeholder validation, coaching, process innovation, and operational excellence while addressing complex cybersecurity and privacy challenges.
Top Skills:
Ai SystemsAWSC++Cloud SecurityData EngineeringData PipelinesDatabricksGCPJavaMachine LearningAzurePythonScikit-LearnSnowflakeTensorFlow

Fintech • Payments • Financial Services
Leads the design and operation of highly available cloud systems, primarily on AWS, using Terraform, GitLab CI/CD, containers, and observability tools. Responsibilities include reliability engineering, incident response, disaster recovery, automation, monitoring, security integration, vulnerability management, and cost optimization. The role builds internal tools, guides architecture, mentors SRE engineers, documents operational processes, and partners with software engineering teams to improve production reliability and compliance.
Top Skills:
Agentic ApplicationsAmazon Api GatewayAmazon AuroraAmazon CloudfrontAmazon CloudwatchAmazon DynamodbAmazon EbsAmazon Ec2Amazon EcsAmazon EfsAmazon RdsAmazon Route 53Amazon S3Amazon VpcAWSAws FargateAws LambdaAws X-RayDastDatadogDockerGitlabGrafanaIamJavaKubernetesLlmsNew RelicNode.jsOwasp Top 10PythonSastSplunkTerraform

Software
Own and scale Drivetrain’s multi-cloud AWS and GCP infrastructure, Kubernetes platforms, CI/CD pipelines, Terraform modules, automation, observability, and security practices. Drive reliability engineering through capacity planning, incident response, postmortems, and SLI/SLO/SLA management. Partner with development teams to improve application deployability, scalability, resilience, and operational efficiency across the SaaS platform.
Top Skills:
AWSAws CloudwatchDockerEfkElkGCPGcp Operations SuiteGitGrafanaIstioJenkinsKubernetesKustomizeLinkerdPrometheusPythonTerraform
Artificial Intelligence • Cloud • Information Technology • Consulting
Internship SRE role responsible for availability, performance, and scalability of an e-commerce supply-chain platform. Tasks include SLO/SLA definition, observability (Prometheus/Grafana/Loki/Tempo/OpenTelemetry), incident response, capacity planning, disaster recovery for PostgreSQL, infrastructure-as-code (Terraform), CI/CD automation, and operational reliability for AI agent services. Mentored by Head of Technology/CTO with potential conversion to full-time based on performance.
Top Skills:
BashCi/CdDockerGrafanaLangchainLlmLokiMakefileNestjsOpentelemetryOracle CloudPgbackrestPostgresql 15PrometheusPythonRedisTempoTerraformTraefik

Healthtech • Software
Staff Site Reliability Engineer responsible for setting infrastructure direction and owning availability, stability, scalability, observability, disaster recovery, and cloud costs for a SaaS platform. The role involves multi-cloud architecture, managed Kubernetes, infrastructure automation, GitOps delivery, incident response, business continuity, technical evaluations, platform migrations, and mentoring engineers. This is a fully remote U.S.-based position with an on-call rotation.
Top Skills:
Cloud ComputingGitopsInfrastructure As CodeKubernetesObservabilityScripting
Healthtech
Site Reliability Engineer responsible for maintaining the reliability, availability, scalability, and performance of enterprise automation platforms. Duties include monitoring, incident response, root cause analysis, observability improvements, deployment support, testing, configuration management, release activities, infrastructure automation, and production risk mitigation. The role partners with development and operations teams to improve system stability and operational readiness across automation solutions.
Top Skills:
AnsibleCi/CdCloud PlatformsDistributed SystemsInfrastructure As CodeMonitoring And AlertingPowershellPythonRpaSeleniumSource Code ManagementTerraform
Legal Tech • Software
Lead observability and incident management efforts: define SLIs/SLOs, build monitoring/alerting, dashboards, logging, and tracing. Drive incident response, postmortems, and reliability improvements to reduce MTTD/MTTR. Integrate observability into CI/CD, maintain AWS and Kubernetes infrastructure, automate operations, and mentor engineers on SRE best practices.
Top Skills:
AWSBashCi/CdDatadogDistributed TracingDynatraceGrafanaKubernetesNew RelicOpentelemetryPowershellPrometheusPython

Sports
Manage and improve CI/CD pipelines, containerized deployments, AWS infrastructure, Terraform resources, monitoring, and incident response for the SportsRecruits platform. Troubleshoot application, database, and distributed-system performance issues; maintain development and QA environments; collaborate with engineering, QA, product, and security teams; and implement automation, observability, scalability, and AI-assisted monitoring improvements.
Top Skills:
Amazon CloudwatchAmazon Ec2Amazon EcsAmazon RdsAws EcrAws LambdaBashBitbucket PipelinesDockerGithub ActionsNew RelicPHPPythonSentryTerraform

Software • Cryptocurrency • Web3
Supports system reliability, scalability, and observability through monitoring, logging, metrics, tracing, alerting, infrastructure as code, automation, production support, incident response, and post-incident improvements. The role collaborates with development and operations teams and uses tools including Prometheus, Grafana, ELK, Terraform, AWS, Docker, and Kubernetes.
Top Skills:
AWSBashDatadogDockerElk StackGoGrafanaKubernetesLinuxOpentelemetryPagerdutyPrometheusPythonTerraformUnix

Cloud • Analytics
Design, operate, and support reliable customer platforms across Linux, Kubernetes, and public cloud environments. Responsibilities include OS lifecycle management, infrastructure automation, IaC, configuration management, GitOps, observability, SLOs, capacity planning, incident response, and on-call support. The role requires depth in one data platform area—Elasticsearch/OpenSearch, Redis, or Kafka-Hadoop-Spark—and willingness to learn others. It also involves customer consultation, platform architecture guidance, documentation, knowledge sharing, and reducing operational toil through scripting and automation.
Top Skills:
AnsibleArgo CdAWSAzureBashCdpChefClouderaCloudFormationConfluentDataprocEfkElasticsearchEmrEvent HubsFluxGCPGitopsGrafanaHadoopHelmKafkaKickstartKubernetesLinuxMskOpensearchPrometheusPuppetPythonRedisSaltSparkTerraform

Blockchain • Fintech • Payments • Financial Services • Cryptocurrency • Web3 • Infrastructure as a Service (IaaS)
Manage AWS and GCP cloud environments, scale infrastructure globally, shape technical architecture, and build reliable CI/CD pipelines. Automate security and compliance controls, improve infrastructure performance, and develop systems interacting with smart contracts across multiple blockchains. The role requires Terraform, shell scripting, GitHub Actions, Docker, production cloud operations, and observability experience, with Kubernetes, networking, and fintech compliance knowledge preferred.
Top Skills:
AWSCi/CdDockerFirewallsGCPGithub ActionsGkeGoHelmInfrastructure As CodeKubernetesLoad BalancersMtlsNode.jsPciShellSsl/TlsTerraformTypescriptVpcZero Trust

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.





Popular Job Searches
All Software Engineer Jobs in Chicago
.NET Developer Jobs in Chicago
Android Developer Jobs in Chicago
Application Engineer Jobs in Chicago
Artificial Intelligence Engineer Jobs in Chicago
Backend Engineer Jobs in Chicago
C# Jobs in Chicago
C++ Jobs in Chicago
Devops Engineer Jobs in Chicago
DevOps Jobs in Chicago
Director Of Software Engineering Jobs in Chicago
Electrical Engineering Jobs in Chicago
Engineering Jobs in Chicago
Engineering Manager Jobs in Chicago
Enterprise Architect Jobs in Chicago
Fpga Engineer Jobs in Chicago
Front-End Developer Jobs in Chicago
Full-Stack Engineer Jobs in Chicago
Golang Jobs in Chicago
Hardware Engineer Jobs in Chicago
Infrastructure Engineer Jobs in Chicago
iOS Developer Jobs in Chicago
Java Developer Jobs in Chicago
Java Full-Stack Engineer Jobs in Chicago
Javascript Jobs in Chicago
Lead Software Engineer Jobs in Chicago
Linux Jobs in Chicago
Perl Jobs in Chicago
PHP Developer Jobs in Chicago
Platform Engineer Jobs in Chicago
Principal Engineer Jobs in Chicago
Principal Software Engineer Jobs in Chicago
Project Engineer Jobs in Chicago
Python Jobs in Chicago
QA Engineer Jobs in Chicago
Reliability Engineer Jobs in Chicago
Ruby Jobs in Chicago
Sales Engineer Jobs in Chicago
Salesforce Developer Jobs in Chicago
Scala Jobs in Chicago
Senior Android Engineer Jobs in Chicago
Senior Devops Engineer Jobs in Chicago
Senior Engineer Jobs in Chicago
Senior Front-End Engineer Jobs in Chicago
Senior Full-Stack Engineer Jobs in Chicago
Senior Java Engineer Jobs in Chicago
Senior Network Engineer Jobs in Chicago
Senior Platform Engineer Jobs in Chicago
Senior Site Reliability Engineer Jobs in Chicago
Senior Software Architect Jobs in Chicago
Senior Solutions Architect Jobs in Chicago
Senior Systems Engineer Jobs in Chicago
Software Engineering Manager Jobs in Chicago
Software Test Engineer Jobs in Chicago
Solutions Architect Jobs in Chicago
Solutions Engineer Jobs in Chicago
Staff Engineer Jobs in Chicago
Staff Software Engineer Jobs in Chicago
Systems Engineer Jobs in Chicago
Web Developer Jobs in Chicago
All Filters
Total selected ()
No Results
No Results
