

Maximum of 25 job preferences reached.
Top Senior Site Reliability Engineer Jobs in Chicago, IL

Aerospace • Information Technology • Security • Cybersecurity • Defense
Leads site reliability engineering for mission-critical cloud platforms, focusing on disaster recovery drills, platform rebuild validation, infrastructure automation, Kubernetes operations, CI/CD, observability, incident response, and system resilience. Collaborates across engineering, security, applications, and data teams while driving remediation and modernization efforts. The role requires deep AWS, Infrastructure as Code, containerization, automation, monitoring, and failure-analysis expertise, plus eligibility for Public Trust clearance.
Top Skills:
AWSAws CloudformationC#Ci/CdCloudwatchDatadogDockerGithub ActionsGitlabGoJavaJenkinsKubernetesPythonTerraformZero Trust

Consumer Web • Gaming • Mobile • News + Entertainment • Software
Own database reliability, scalability, and operational excellence across cloud and on-premises environments. Build automated Kubernetes-based database platforms, infrastructure tooling, failover and backup systems, and self-healing capabilities. Lead observability, performance optimization, capacity planning, incident response, and safe migration practices. Partner with application teams, leverage AI for operational improvements, mentor engineers, influence architecture, and drive technical strategy for highly available database infrastructure.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorEksFluxcdGithub CopilotGitopsGkeGoKubernetesKubernetes OperatorsMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform

Reposted One Month AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
As a Senior Site Reliability Engineer, you'll design and build complex systems, support Atlas platform operations, automate processes, and ensure high availability of services.
Top Skills:
AWSAzureDnsGCPGoHTTPLinuxPythonRubyTls
Fintech • Software • Financial Services
Lead the SRE function for NinjaTrader’s trading platform, ensuring availability, scalability, performance, and 99.95% uptime. Responsibilities include managing Kubernetes services, resolving production incidents, participating in a 12x7 on-call rotation, automating deployments and operational tasks, designing monitoring and alerting systems, establishing SLIs/SLOs, using Terraform for infrastructure automation, and implementing cloud security and compliance practices. The role also mentors engineers and collaborates cross-functionally on reliable platform delivery.
Top Skills:
AnsibleAWSAzureBashDatadogDockerGCPGithub ActionsGoGrafanaHelmKubernetesPci DssPrometheusPythonSoc 2Terraform
Artificial Intelligence • Cybersecurity
Own and evolve the company-wide SRE strategy, reliability standards, observability practices, incident management, service ownership, SLOs, and on-call operations. Lead cross-functional reliability initiatives, establish dashboards, alerts, runbooks, and escalation paths, improve production readiness and incident response, and operate large-scale distributed systems across AWS and Kubernetes. Participate in a 24/7 on-call rotation and help shape the SRE function.
Top Skills:
Argo CdAWSDatadogGitlab CiGitopsGrafanaKubernetesNew RelicPythonTerraform

Other • Retail
Lead and develop an SRE team responsible for the reliability, availability, performance, automation, and observability of Linux-based digital commerce infrastructure. Set SRE and DevOps strategy, modernize Kubernetes and CI/CD practices, establish automation and infrastructure-as-code standards, oversee incident response, and drive SLIs, SLOs, and error budgets. Partner across engineering, architecture, infrastructure, security, networking, and product teams while recruiting, mentoring, and developing SRE talent.
Top Skills:
Apache TomcatCi/CdDatadogDockerError BudgetsF5Github ActionsInfrastructure As CodeJfrog ArtifactoryKubernetesLinuxNginxPuppetPythonSlis/SlosTerraformVMware

One Month AgoSaved
Easy Apply
Easy Apply
Fintech • News + Entertainment • Software • Financial Services
Build fault-tolerant, self-healing infrastructure and internal tooling for a brokerage platform. Expand observability using Prometheus, Honeycomb, OpenTelemetry, and Grafana; scale HashiCorp Nomad services through capacity planning and load testing; establish SLOs, error budgets, and alerting; analyze Linux and networking performance; support production on-call operations; and mentor engineers in site reliability practices.
Top Skills:
ConsulElixirGrafanaHashicorp NomadHoneycombJavaLinuxMulticastOpentelemetryPrometheusPythonRubyTcp/IpUdpVault

Edtech • Fintech • Information Technology • Software
Operate and improve AWS production infrastructure, infrastructure as code, Kubernetes workloads, observability, CI/CD, and incident response. The role investigates root causes, strengthens application resilience, automates operational tasks, supports database and performance reliability, maintains documentation, and participates in 24/7 on-call rotations. The engineer owns scoped reliability projects and collaborates with product engineering teams on resilient, secure, and compliant systems.
Top Skills:
Amazon EksAmazon RdsAWSCircleCIDatadogGithub ActionsKubernetesLinuxNew RelicOpensearchPostgresRedisRubyRuby On RailsTerraform

Hardware • Healthtech
Owns the reliability, security, performance, and availability of AWS-hosted healthcare infrastructure. Builds infrastructure as code, CI/CD automation, monitoring, observability, backup and disaster recovery capabilities. Leads incident response, optimizes cloud resources, implements security controls, supports customer onboarding and migrations, and ensures compliance with healthcare privacy and software lifecycle requirements. Participates in on-call rotations and provides technical guidance to engineering and support teams.
Top Skills:
AWSBashCi/CdCitrixEcsGdprHipaaHyper-VIec 62304JavaScriptJinjaJSONMirth ConnectPythonTerraformTypescriptVMwareYaml

Healthtech • Software
Owns reliability, availability, incident response, and infrastructure for a regulated SaaS platform. Maintains AWS and Azure environments using Terraform, operates Kubernetes production systems, develops automation, improves observability and deployment safety, mentors engineers, and helps establish the company’s reliability practice.
Top Skills:
AWSAzureBashCloudwatchGrafanaKubernetesPrometheusPythonTerraform

Information Technology • Consulting
Administer and secure the organization’s GitHub environment, including repositories, permissions, branch protections, security controls, and CI/CD workflows. Build automation with GitHub Actions, APIs, and scripting; monitor reliability against SLOs; troubleshoot incidents; and improve developer experience. Integrate identity providers and security tools, support migrations, maintain documentation, and guide teams on GitHub usage and Copilot adoption. The role requires SRE or DevOps experience, infrastructure-as-code, containers, cloud platforms, and observability tooling.
Top Skills:
AnsibleAWSAzureBashCodeqlDatadogDependabotDockerGCPGithub ActionsGithub ApiGithub CliGithub CopilotGithub EnterpriseGrafanaPowershellPrometheusPythonSAMLScimSplunkSsoTerraform
Artificial Intelligence • Cloud • Fintech • Information Technology • Analytics • Financial Services • Cybersecurity
Defines enterprise reliability architecture and resiliency strategies for critical platforms. Creates reliability guidelines, reference architectures, maturity models, and governance standards; supports incident response and root cause analysis; develops infrastructure configuration, application lifecycle, observability, and deployment automation; and contributes hands-on code. Partners with technology, product, development, and operations teams to improve availability, fault tolerance, operational maturity, and consistency across cloud and on-premises environments.
Top Skills:
AlertingAnsibleArmBicepC#ChefCi/CdCloud InfrastructureDashboardsDistributed SystemsInfrastructure As CodeJavaLoggingMetricsNetworkingObservabilityOn-Premises InfrastructurePuppetPythonTerraformTracing
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free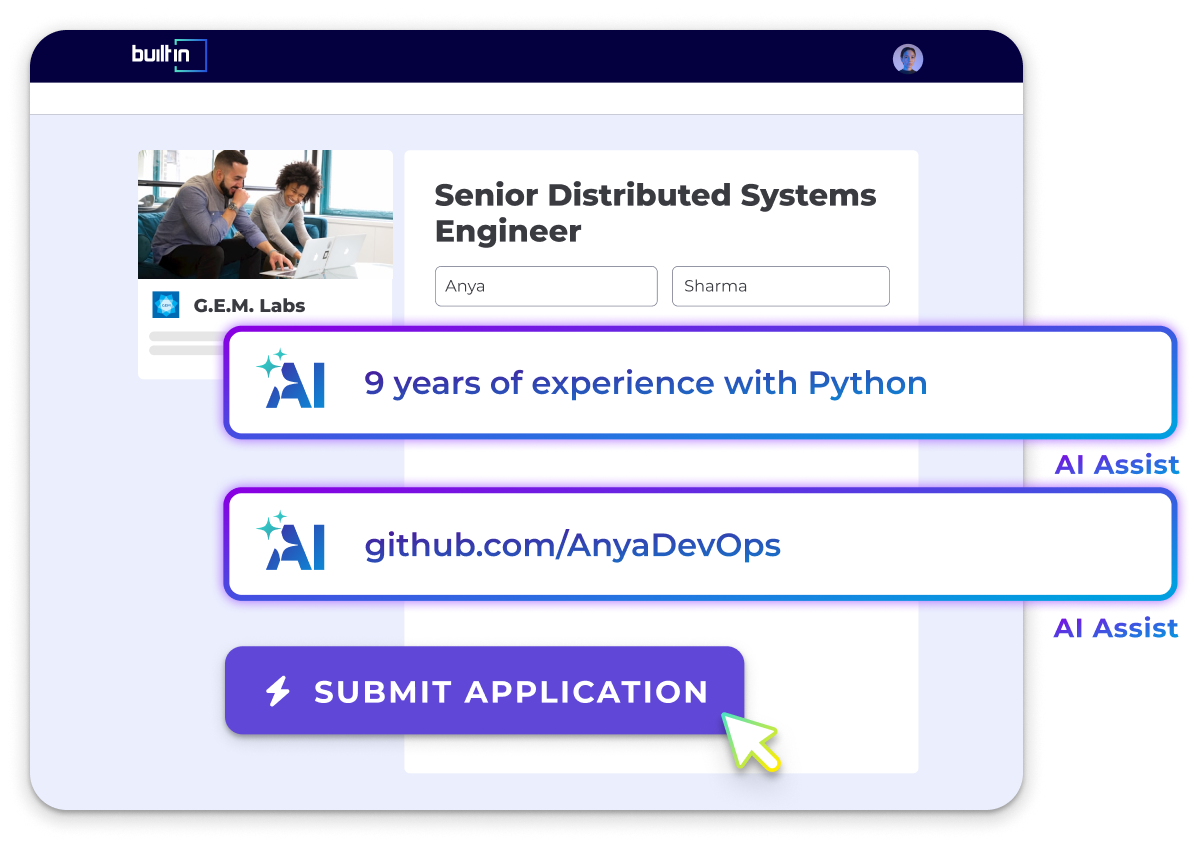
Fintech
Lead SRE work partnering with development teams to design and implement availability, scalability, observability, and automation for production systems. Build tooling, manage incident response and RCAs, optimize capacity and performance, mentor engineers, maintain runbooks, and participate in a 24x7 on-call rotation.
Top Skills:
AuroraAWSChefCi/CdDockerDynamoDBGitGoIpJavaJavaScriptJenkinsJmsKafkaKubernetesLinuxMavenMemcachedMicroservicesObservabilityOraclePythonRedisRubySqsSwarmTcpUdp
Fintech
Provides enterprise-level technical leadership for site reliability engineering across production services. Improves reliability, scalability, observability, deployment, automation, incident response, resilience, capacity management, and operational readiness. Establishes SLIs, SLOs, error budgets, and technical direction while partnering with software engineering teams. Leads critical incident response, reduces operational toil, and develops reusable engineering practices, tooling, and platforms that improve organizational capability.
Top Skills:
AlertingAWSCi/CdContainersDistributed SystemsGoogle Cloud PlatformInfrastructure As CodeLinuxAzureMonitoringObservabilityOracle Cloud InfrastructureOrchestrationScriptingSoftware AutomationUnix
Software • Defense
Own reliability, scalability, security, observability, and incident response for production applications across AWS and on-premises DoD environments. Build monitoring and alerting, define SLIs and SLOs, lead post-incident reviews, automate infrastructure with Terraform and Ansible, operate Kubernetes clusters, embed RMF and STIG controls, reduce operational toil, and support secure air-gapped deployments.
Top Skills:
AlloyAnsibleAWSAws GovcloudBashDatadogElk StackGithub ActionsGitlab Ci/CdGitopsGoGrafanaHyper-VIstioJenkinsKubernetesLinkerdLokiNutanixPrometheusProxmoxPythonRmfSecurity+StigsTerraformVMware

Information Technology • Security • Cybersecurity
Own production operations and highly available cloud infrastructure for regulated government environments. Lead incident response, root-cause analysis, disaster recovery testing, compliance operationalization, audit readiness, vulnerability management, and continuous monitoring. Build automation, secure CI/CD pipelines, infrastructure-as-code, observability, and compliance tooling across Kubernetes, Linux, containers, and cloud platforms. Partner with security, compliance, and engineering teams to improve reliability, deployment safety, and regulatory sustainment.
Top Skills:
Aws GovcloudBashCi/CdDod Il4Dod Il5FedrampGitopsGoGrafanaKubernetesLinuxNist 800-53PrometheusPythonStigTerraformUnixZero Trust
Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
AdTech
Design, build, and scale cloud-native infrastructure with automation-first approach. Develop Terraform modules, Helm charts, Istio routing, observability (Prometheus/Grafana/Datadog), maintain GCP databases, improve CI/CD, and use AI agents to automate and operationalize reliability and developer experience.
Top Skills:
Amazon KinesisAWSAws LambdaAws SnsCi/CdClaude CodeCloudsqlCursorDatadogDockerGCPGitlabGoogle BigqueryGoogle Cloud FunctionsGoogle Cloud RunGoogle Pub/SubGoogle SpannerGrafanaHelmIstioKafkaKubernetesMySQLPrometheusSQLTerraform

Artificial Intelligence • Fintech • Software • Automation
Own and improve the reliability of Kintsugi’s AWS and managed Kubernetes infrastructure. Build automation, internal tools, observability, CI/CD pipelines, and infrastructure-as-code workflows while reducing operational toil. Lead incident response, reliability architecture, developer enablement, cost optimization, security, compliance, and disaster recovery efforts. Work agent-first and partner with Platform Engineering, Product, QA, and software teams to deliver scalable, secure systems.
Top Skills:
AWSCi/CdCloudFormationInfrastructure As CodeKubernetesObservabilityPostgresRedisTerraform

Artificial Intelligence • Cloud • Machine Learning • Software • Database • App development • Generative AI
Lead reliability engineering for Replit’s large-scale infrastructure by designing observability, defining SLOs and SLIs, leading incident response, automating operations, optimizing Kubernetes and GCP deployments, debugging distributed systems, and mentoring engineers. Build internal tools and integrations in Python or Go, maintain infrastructure as code and CI/CD pipelines, improve system performance and resilience, and establish reliability, security, and operational best practices across the engineering organization.
Top Skills:
Ci/CdDatadogDockerGoGoogle Cloud Platform (Gcp)GrafanaKubernetesOpentelemetryPrometheusPulumiPythonTerraform

Cloud • Software • Analytics
Develop and operate Arista’s FedRAMP CloudVision SaaS platform at scale. Responsibilities include improving reliability, scalability, observability, autoscaling, disaster recovery, capacity planning, CI/CD, network architecture, cost optimization, and cloud application security. The role develops and manages Kubernetes-native services, distributed databases, and automation using technologies such as GCP, GKE, Go, Python, Ansible, Pulumi, and Bash. Participation in a FedRAMP on-call rotation is required.
Top Skills:
AnsibleBashCi/CdDistributed DatabasesFedrampGoGoogle Cloud Platform (Gcp)Google Kubernetes Engine (Gke)KubernetesPulumiPythonSaaS

Fitness • Healthtech • Software
Own reliability and security of CI/CD and production services: define SLI/SLOs, lead incident response and postmortems, build observability (Datadog), operate Kubernetes and IaC (Terraform), harden pipelines with SAST/DAST/SCA and policy-as-code, and coach teams on reliability and operational best practices.
Top Skills:
AWSCi/CdConftestDastDatadogDockerGithub ActionsGoInfrastructure As CodeKubernetesKyvernoOpa/RegoPythonSastScaTerraformTypescript
Legal Tech • Software
Design and improve observability (monitoring, logging, tracing, SLIs/SLOs), build automation and CI/CD, lead incident response and reliability improvements, mentor SREs, run on-call, and apply AI/ML to operational signals to forecast and reduce risks.
Top Skills:
AWSBashCi/CdDistributed TracingGoInfrastructure As CodeKubernetesLoggingMonitoringPythonSlisSlos
Fintech • Real Estate • Software
Lead reliability and observability efforts across the org: design and maintain Kubernetes and AWS infrastructure, build CI/CD pipelines, drive IaC standards (Terraform/Crossplane), partner with 16+ teams to roll out tools and processes, participate in on-call rotation and incident response, and use AI tools to accelerate work.
Top Skills:
Ai ToolsArgoAurora PostgresAWSCi/Cd PipelinesCrossplaneDatadogDocumentdb (Mongo)EcsEksGithub ActionsHelmKubernetesMongoDBPostgresRdsTerraform
Cloud • Security • Software • Cybersecurity
Architect, build, and support reliable network infrastructure and automation for Akamai’s distributed cloud platform. Develop Bash and Python tooling, establish deployment standards, define SLOs, mentor engineers, and troubleshoot complex network issues. The role requires expertise in large-scale distributed systems, TCP/IP, BGP, Linux networking, configuration management, CI/CD, and open-source networking software, with participation in on-call rotations.
Top Skills:
AnsibleArgocdBashBgpBirdChefFirewallsFrrGithub ActionsGoGobgpJenkinsLinux NetworkingLoad BalancingPuppetPythonRustSaltstackSlack BotsTcp/Ip
5 Days AgoSaved
Cloud • Security • Software • Cybersecurity
Develop and operate Akamai’s Linux-based cloud infrastructure, including bare-metal and virtual machine platforms, kernels, operating systems, and KVM/QEMU virtualization. Build software, automation, observability, and infrastructure enhancements at scale; troubleshoot complex distributed-system issues; collaborate across engineering and operations; mentor team members; and participate in on-call service restoration.
Top Skills:
AnsibleChefKubernetesKvm/QemuLinuxLinux KernelNested VirtualizationPuppetSaltstack

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Chicago, IL Companies Hiring Senior Site Reliability Engineers
See All






Popular Job Searches
All Software Engineer Jobs in Chicago
.NET Developer Jobs in Chicago
Android Developer Jobs in Chicago
Application Engineer Jobs in Chicago
Artificial Intelligence Engineer Jobs in Chicago
Backend Engineer Jobs in Chicago
C# Jobs in Chicago
C++ Jobs in Chicago
Devops Engineer Jobs in Chicago
DevOps Jobs in Chicago
Director Of Software Engineering Jobs in Chicago
Electrical Engineering Jobs in Chicago
Engineering Jobs in Chicago
Engineering Manager Jobs in Chicago
Enterprise Architect Jobs in Chicago
Fpga Engineer Jobs in Chicago
Front-End Developer Jobs in Chicago
Full-Stack Engineer Jobs in Chicago
Golang Jobs in Chicago
Hardware Engineer Jobs in Chicago
Infrastructure Engineer Jobs in Chicago
iOS Developer Jobs in Chicago
Java Developer Jobs in Chicago
Java Full-Stack Engineer Jobs in Chicago
Javascript Jobs in Chicago
Lead Software Engineer Jobs in Chicago
Linux Jobs in Chicago
Perl Jobs in Chicago
PHP Developer Jobs in Chicago
Platform Engineer Jobs in Chicago
Principal Engineer Jobs in Chicago
Principal Software Engineer Jobs in Chicago
Project Engineer Jobs in Chicago
Python Jobs in Chicago
QA Engineer Jobs in Chicago
Reliability Engineer Jobs in Chicago
Ruby Jobs in Chicago
Sales Engineer Jobs in Chicago
Salesforce Developer Jobs in Chicago
Scala Jobs in Chicago
Senior Android Engineer Jobs in Chicago
Senior Devops Engineer Jobs in Chicago
Senior Engineer Jobs in Chicago
Senior Front-End Engineer Jobs in Chicago
Senior Full-Stack Engineer Jobs in Chicago
Senior Java Engineer Jobs in Chicago
Senior Network Engineer Jobs in Chicago
Senior Platform Engineer Jobs in Chicago
Senior Site Reliability Engineer Jobs in Chicago
Senior Software Architect Jobs in Chicago
Senior Solutions Architect Jobs in Chicago
Senior Systems Engineer Jobs in Chicago
Software Engineering Manager Jobs in Chicago
Software Test Engineer Jobs in Chicago
Solutions Architect Jobs in Chicago
Solutions Engineer Jobs in Chicago
Staff Engineer Jobs in Chicago
Staff Software Engineer Jobs in Chicago
Systems Engineer Jobs in Chicago
Web Developer Jobs in Chicago
All Filters
Total selected ()
No Results
No Results
